gpt-image-1 Deprecated: Migrating to GPT Image 2.5
gpt-image-1 shuts down 2026-10-23, gpt-image-1.5 2026-12-01. What changes in the API (quality tiers, input_fidelity, sizes) and which 2.5 model to move to.
Last updated: 2026-09-20
Two shutdown dates are on the calendar: gpt-image-1 on 2026-10-23 and gpt-image-1.5 on 2026-12-01. As of this page's last update that is a little over a month and a little over ten weeks. If you have either model string in production, this page is the shortest path to GPT Image 2.5: what changes in the request, what you now have to choose that you did not have to choose before, and what to test before you flip the string.
The dates
| Model | Announced | Shutdown date | Replacement named by OpenAI |
|---|---|---|---|
gpt-image-1 | 2026-04-22 | 2026-10-23 | gpt-image-2 |
gpt-image-1-mini | 2026-06-02 | 2026-12-01 | gpt-image-2 |
gpt-image-1.5 | 2026-06-02 | 2026-12-01 | gpt-image-2 |
Those rows are OpenAI's deprecations table, checked 2026-09-20. Note what it names as the replacement: gpt-image-2, not 2.5, because the entries predate the 2.5 launch. gpt-image-2 itself is not deprecated. This page covers moving to 2.5, which is where the current models and the current documentation are; the two 2.5 models take the same request as gpt-image-2 and are listed at the same per-token prices, so nothing below stops you landing on gpt-image-2 first if that is what your dependency pins.
What you are migrating to
GPT Image 2.5 is two models with one price and one parameter set:
| Model | Position |
|---|---|
gpt-image-2.5-flare | small, speed-optimised: comparable quality to gpt-image-2, and faster |
gpt-image-2.5-sunburst | base, quality-optimised: higher quality than gpt-image-2 |
Both support generation, editing and transparent backgrounds, and both take the identical request. In our own measurements they returned identical output-token counts at every quality tier, so which one you pick does not change your per-image price (see the cost page). What differs is time: Sunburst took 1.18× Flare's time at low and 2.26× at max (the speed page).
What changes in the request
Two differences between GPT Image 1/1.5 and 2.5 are documented. Everything else in this section is the 2.5 parameter set as documented, which you should validate your requests against rather than assume unchanged.
1. input_fidelity goes away
input_fidelity (low / high) is a GPT Image 1 and 1.5 parameter. GPT Image 2 and 2.5 do not accept it. Remove it from every request. If you were using high fidelity to keep a reference image's details, the 2.5 route is to describe the reference's role in the prompt — which image controls what, and which traits must survive — and to write edits as one change followed by a list of what must not move. See prompt rules.
2. Two new quality tiers above high
GPT Image 1 and 1.5 offered low, medium, high and auto. GPT Image 2.5 adds xhigh and max. Your existing quality values still exist, so a request that sent high keeps working. Two things change in practice:
autois a different decision now. With six tiers available, and two models that each pick their own effort underauto, a request that relied on the default is no longer predictable in cost or time. Set the tier explicitly.- The top of the range is far more expensive. For our 1024×1024 prompt,
maxreturned 7,024 output tokens against 1,756 athigh, four times the price. Do not migrate ahighworkload tomaxbecause it exists. Migrate it tohigh, measure, and move only if a specific requirement fails.
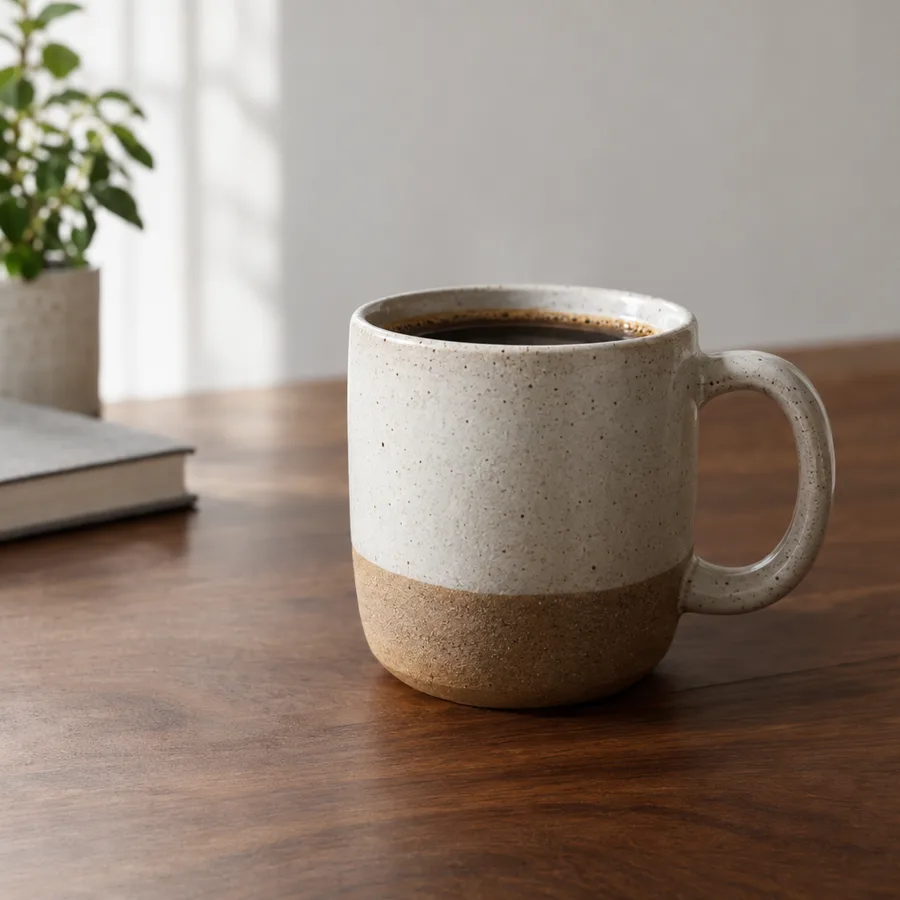
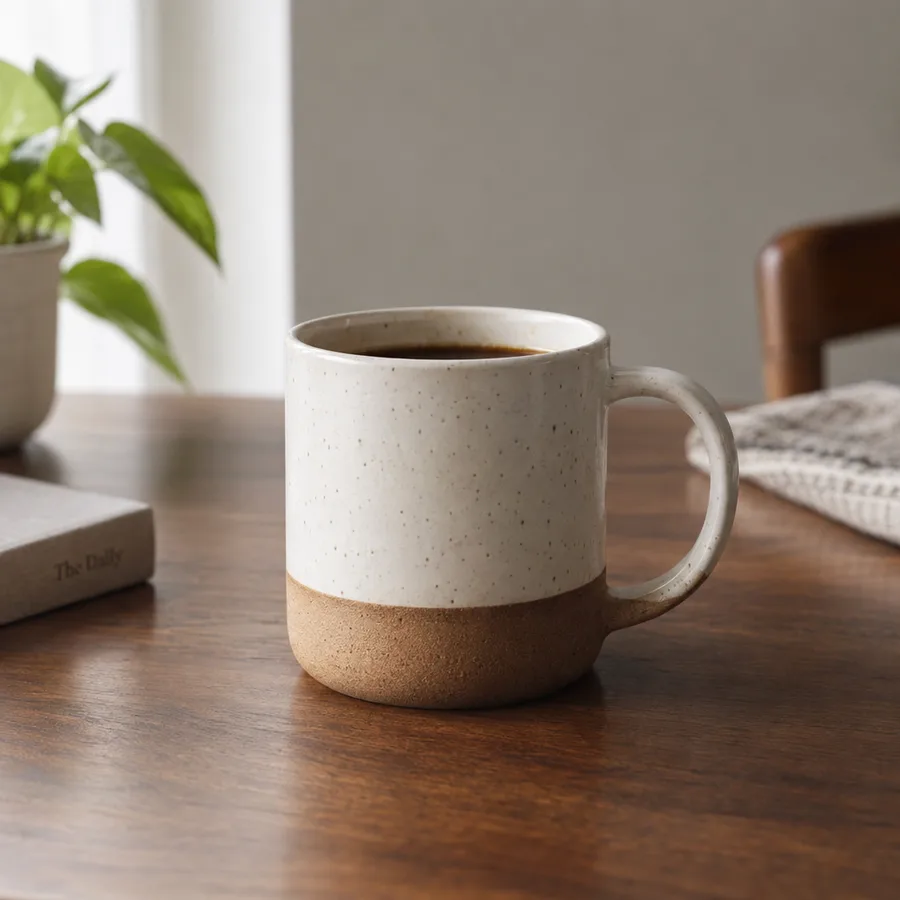
If you were on high, this is what high looks like on both 2.5 models for the same prompt:
The 2.5 parameter set
Validate against these; the constraints on size in particular are strict.
quality:auto,low,medium,high,xhigh,max.size:auto, or anyWIDTHxHEIGHTwhere both sides are multiples of 16, no side exceeds 3,840 px, the aspect ratio is at most 3:1, and the total is between 655,360 and 8,294,400 pixels. Presets:1024x1024,1536x1024,1024x1536,2048x2048,2048x1152,3840x2160,2160x3840.background:auto,opaque,transparent. Transparent output needs PNG or WebP; check the alpha channel around hair, glass, shadows and object edges.output_format:png,jpeg,webp.output_compression: 0–100, JPEG and WebP only.n: number of variants.
If any size in your code is not a multiple of 16 on both sides, it will need to change. 1024x1024 and the other presets are safe.
Which model to migrate to
OpenAI's guidance, which matches what we measured:
- If your current quality is already acceptable, start with Flare. Same prompt, same size, an explicit tier. If it passes, you have banked the latency gain.
- If your current model was not good enough for complex scenes, start with Sunburst. Get the output acceptable there first.
- Then run the same prompt through Flare and switch only if the quality still passes and the latency gain is real for your prompts.
Some rules of thumb from our tests, all at the same price per image:
- Running
lowormedium: Sunburst, because the extra wait was 2–6 seconds. - Running
highor above in a flow where a person waits: Flare, because the gap was 15–63 seconds. - Consistency across frames, legible in-image text, close-up faces: Sunburst — or both, with Sunburst making the reference and Flare running the scenes (consistent characters).
- A single-model migration is fine; a two-model one is easy, because both accept the identical request. Read the single-model pages for Flare and Sunburst before choosing.
Migration checklist
- Swap the model string to
gpt-image-2.5-flareorgpt-image-2.5-sunburst. - Delete
input_fidelityfrom every request. - Set
qualityexplicitly; do not carry over a reliance onauto. - Check every
sizeagainst the multiple-of-16, 3:1 and pixel-count constraints. - If you use transparency, confirm
background: "transparent"with PNG or WebP output and inspect the alpha channel on real outputs. - Re-run your prompt test set on the new model. Do not assume the same prompt produces the same picture; treat the migration as a model change, because it is one.
- Time the two models on your own prompts at your own tier, not on ours. Our numbers are one run per cell from one region; yours will differ.
- Read
output_tokensfrom a few responses and recompute your unit cost at $30 per million image-output tokens.
Step 7 takes a minute in the studio: paste a production prompt, pick the tier you ship, run it on one model and then the other, and read the seconds and tokens off each image.
FAQ
Will my gpt-image-1 prompts work on 2.5?
The request format does, minus input_fidelity. Whether the picture is what you want is a separate question, so test your prompt set. OpenAI's prompting guide for 2.5 is worth a read before you tune anything: say "photorealistic" explicitly when you want it, put in-image text in quotes, and write edits as change-then-keep.
Should I move to gpt-image-2 instead?
OpenAI's deprecations table names gpt-image-2 as the replacement, and it is a valid landing point: same request shape, same per-token prices as 2.5. This page does not benchmark it. The 2.5 models are the ones OpenAI positions above it — Flare at comparable quality and faster, Sunburst at higher quality — and they are what the current documentation describes, so if you are touching the integration anyway, 2.5 is the shorter road.
Do I have to choose between Flare and Sunburst up front? No. They take the same request, so the model string can be a configuration value. Many teams will end up with both: Flare where a person waits, Sunburst where the output is final.
Does the price change?
Per token, it goes down. OpenAI's price list (checked 2026-09-20) has gpt-image-1 at $40 per million image-output tokens with image input at $10 per million, gpt-image-1.5 at $32 per million output, and both 2.5 models at $30 per million output with image input at $8 per million. Per image depends on the token counts each model returns for your request, and they need not match across generations, so compare output_tokens from both at the tier you ship.
Is the gpt-image-1.5 deadline different from the gpt-image-1 one?
Yes: gpt-image-1.5 shuts down on 2026-12-01, 39 days after gpt-image-1 on 2026-10-23.
Sources
- OpenAI model deprecations — announcement and shutdown dates, replacement model; checked 2026-09-20
- OpenAI image prompting guide — 2.5 parameters and prompting guidance
- OpenAI API pricing — per-token rates for gpt-image-1, 1.5 and both 2.5 models; checked 2026-09-20
- OpenAI Devs launch post
- Our runs: 2026-09-12, 1024×1024, one run per cell