GPT Image 2.5 Speed: Flare vs Sunburst Latency by Tier
Flare vs Sunburst latency at every GPT Image 2.5 tier: 11 vs 13 s at low, 50 vs 113 s at max. Why the ratio climbs from 1.18× to 2.26×, and the n=1 caveat.
Last updated: 2026-09-20
How fast is GPT Image 2.5? There is no single number: the wait depends on which model you pick and, above all, on the quality tier. We timed both models at every tier with the same prompt and size, and the gap between them is not a constant — it grows with the tier.
The test
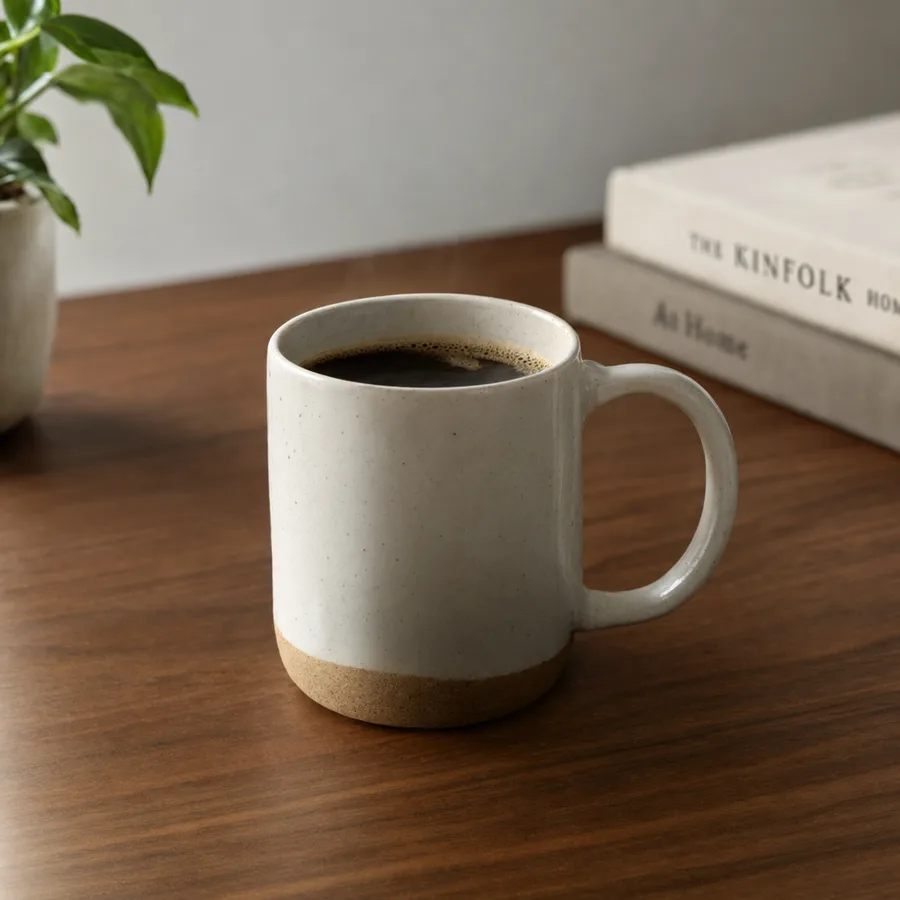
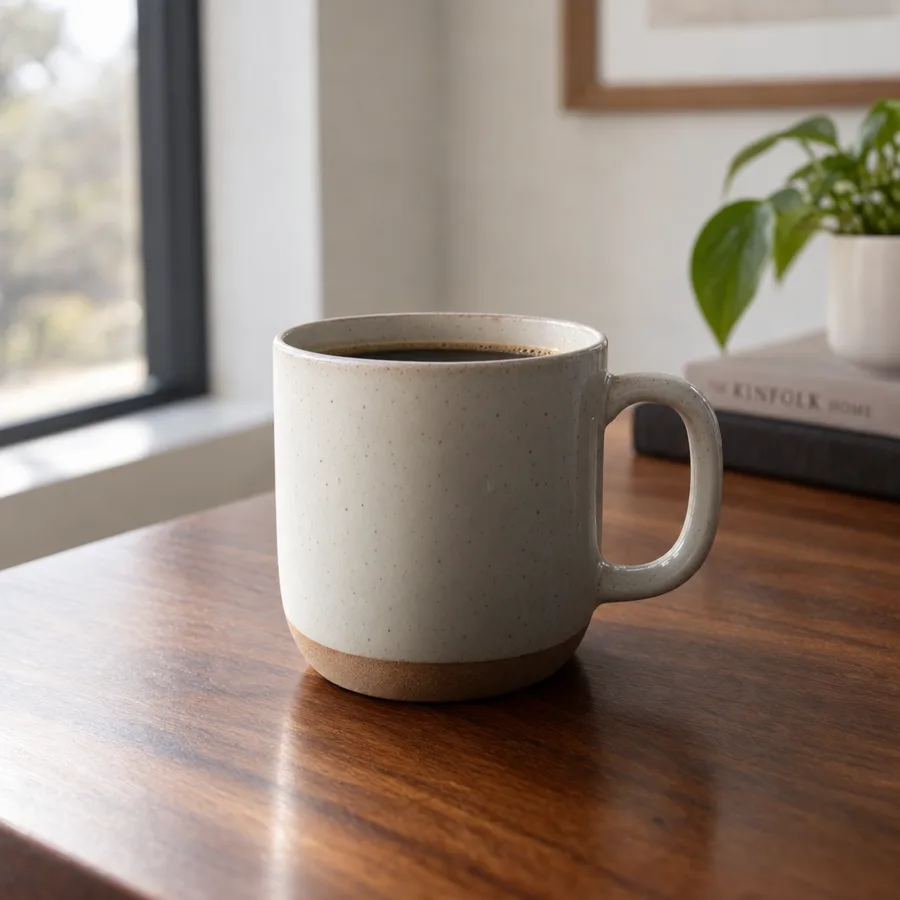
One prompt — a photorealistic product shot of a ceramic mug on a walnut table — at 1024×1024, on gpt-image-2.5-flare and gpt-image-2.5-sunburst, at each of the five explicit quality tiers, one run per cell, serial, from one region in one session on 2026-09-12. The seconds below are the generation time the API reported for each job.
| Quality | Flare | Sunburst | Sunburst ÷ Flare | Sunburst − Flare | Output tokens (both) |
|---|---|---|---|---|---|
low | 11 s | 13 s | 1.18× | +2 s | 196 |
medium | 10 s | 16 s | 1.60× | +6 s | 439 |
high | 20 s | 35 s | 1.75× | +15 s | 1,756 |
xhigh | 26 s | 54 s | 2.08× | +28 s | 3,122 |
max | 50 s | 113 s | 2.26× | +63 s | 7,024 |
Finding 1: the gap grows with the tier
The ratio climbs monotonically: 1.18×, 1.60×, 1.75×, 2.08×, 2.26×. At low, Sunburst costs you two seconds. At max, it costs you a minute. "Sunburst is twice as slow" is true at xhigh and max and simply false at low and medium.
This is why the community numbers disagree. A 17 s Flare and a 35 s Flare are both plausible readings of the same model at different tiers, and the 2× figure people quote for Sunburst comes from measurements at high or above. If you are told a single latency for either model, ask which tier.
It also changes the decision. If your product runs low or medium, the speed argument for Flare is worth 2–6 seconds; at the same price per image (the cost page has the numbers), Sunburst is the easy default. The trade-off only becomes real from high upwards, and at max it is 63 seconds a person may be waiting through.
Finding 2: Sunburst's time grows with the prompt, Flare's barely moves
Holding the tier at high and changing only the prompt:
Prompt (high, 1024×1024) | Flare | Sunburst | Ratio |
|---|---|---|---|
| Product shot, one object | 20 s | 35 s | 1.75× |
| Bookshop interior, many elements | 25 s | 44 s | 1.76× |
| 16-frame sprite sheet, one character | 24 s | 47 s | 1.96× |
| Cafe portrait, six deliberate checkpoints | 20 s | 44 s | 2.20× |
Flare stayed inside 20–25 s. Sunburst went from 35 s to 47 s. The pattern looks like a fixed budget on Flare and effort that scales with the scene on Sunburst — a description, not a mechanism; we can see the timings, not the model. Practically: the more you pack into a Sunburst prompt, the longer you wait. The busiest high prompt (47 s) landed closer to the xhigh product shot (54 s) than to the high product shot (35 s). It is also the run where Sunburst's extra time bought something measurable; see consistent characters.
What the seconds are and are not
- They are per-job generation times from the API, not our stopwatch. Our own end-to-end wall clock — submit, poll, receive the file — ran about one to three seconds longer on every row. Reproduce this with your own client and expect your numbers to sit a little above ours.
- They are n=1. One run per cell, one region, one time window. A single slow job would move a cell by several seconds, and at
lowandmediumthe difference between models is inside that noise. The direction of the curve is consistent across all five tiers and across the fourhighprompts, which is why we publish it; the individual cells are not precise to the second. - They are text-to-image only. Editing has its own timing, and we have not measured it.
- They went through an API gateway, not a direct OpenAI endpoint. Any gateway overhead is inside the numbers and applies to both models equally.
Round two will run each cell at least three times and report medians and spread. Until then, treat the table as a first measurement whose every row you can rerun from the prompts published here.
How to time it yourself
- Fix the tier. Never compare on
auto; each model picks its own effort level underautoand you would be timing two different jobs. - Fix the size and the prompt, and send the identical request to both model IDs,
gpt-image-2.5-flareandgpt-image-2.5-sunburst. - Run each cell more than once and keep the median. Our n=1 is the floor for a first look, not a standard.
- Record output tokens alongside seconds. If the token counts differ between models for the same request, something other than the model changed.
Or use the studio: pick a tier, run your prompt on one model, then run it on the other with one click. It reports seconds and output tokens for every image.
FAQ
Is Flare always faster than Sunburst?
In every text-to-image cell we ran, yes — by 2 s at low and 63 s at max. A community report suggests edit rounds can overlap; unverified.
Does a longer prompt slow Flare down?
Not measurably in our runs: 20–25 s across four high prompts of very different complexity, and adding ten exclusion lines to the bookshop prompt left Flare at 25 s. Sunburst moved from 35 s to 47 s across the same prompts.
Which tier should I benchmark at?
The one you will ship. The ratio changes with the tier, so a high benchmark tells you nothing reliable about medium.
Why is Flare's medium faster than its low?
10 s against 11 s is inside n=1 noise. Do not read a trend into a one-second difference between two single runs.
Sources
- Our runs: 2026-09-12, 1024×1024, one run per cell; prompts and outputs on this site, scripts in the repository